


React SEO: The Best Optimization Methods for React Websites
In this article, you can find examples of how SEO efforts can work with React and how Google crawls these types of websites. You can apply the recommendations in this article when changing your infrastructure or building a new website.
There is almost one central issue behind SEO problems in React: should we render the content in the browser or on the server? In this article, I will answer these questions in detail.
Before getting into SEO, we can understand from the example below how Google crawls JavaScript and which stages it uses before adding pages to its index. A page goes through many stages before it is indexed and then becomes part of the index. Considering the number of pages Google crawls every day, if Googlebot is given a smooth experience, it can fully crawl the content, add it to the index, and rank the page.
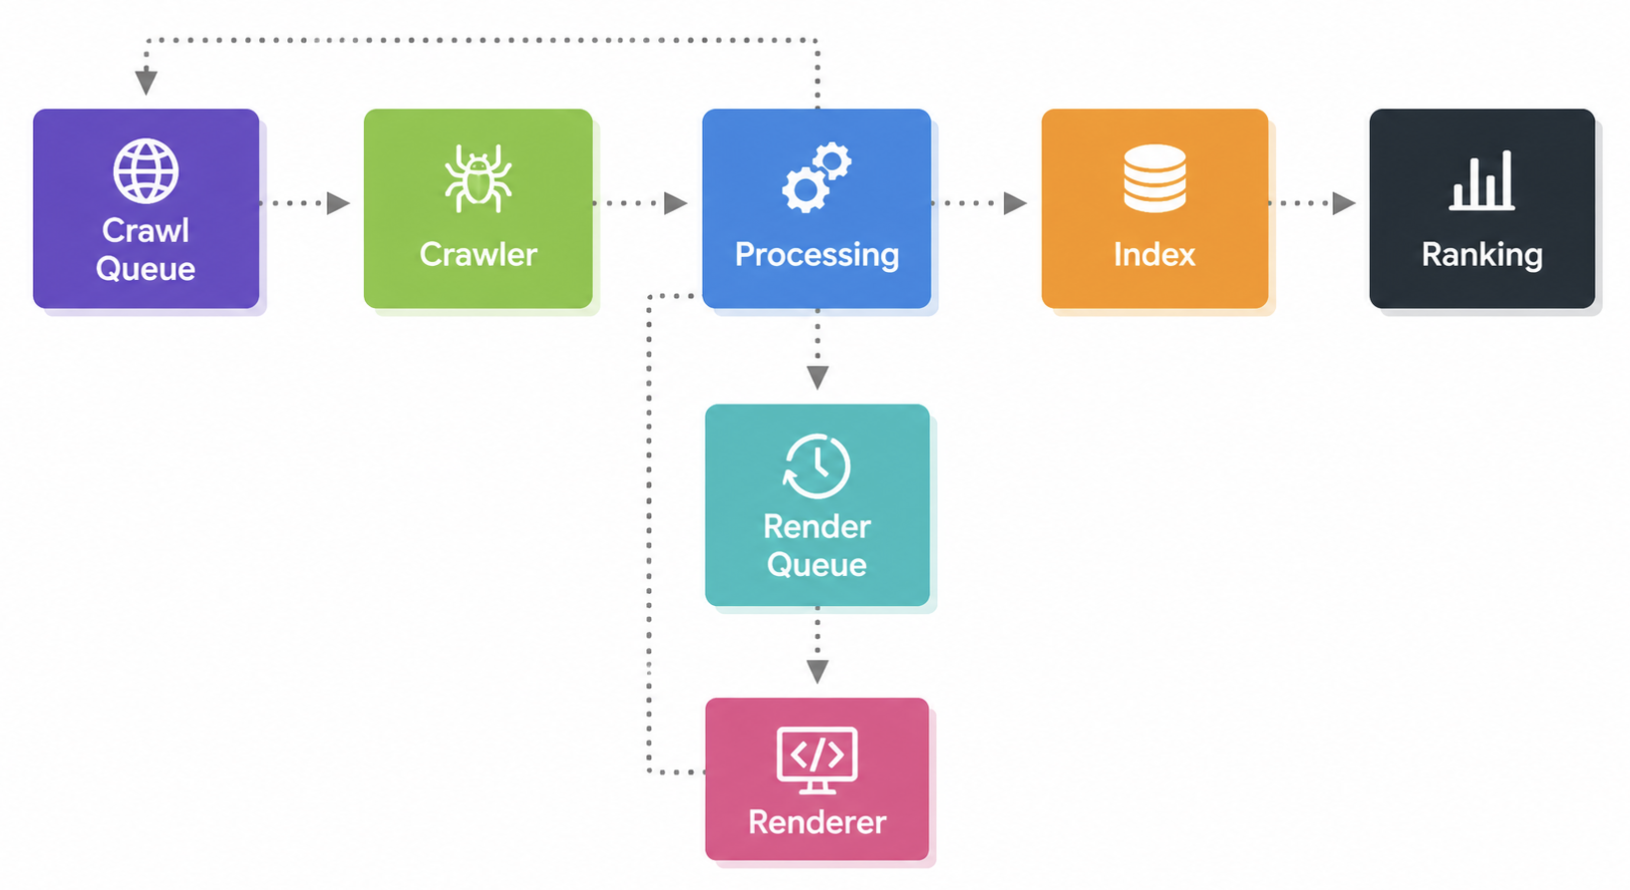
- Rendering works separately from crawling. Content delivered through JavaScript enters the index later.
- Rendering is not always guaranteed. Because of rendering timeouts, JS errors, or JS and API resources blocked by robots.txt, Googlebot may see the page as empty.
- On publisher sites where stock and price changes are constant, such as e-commerce sites, or where news content is added very frequently, these delays can lead to commercial losses if they are not managed properly.
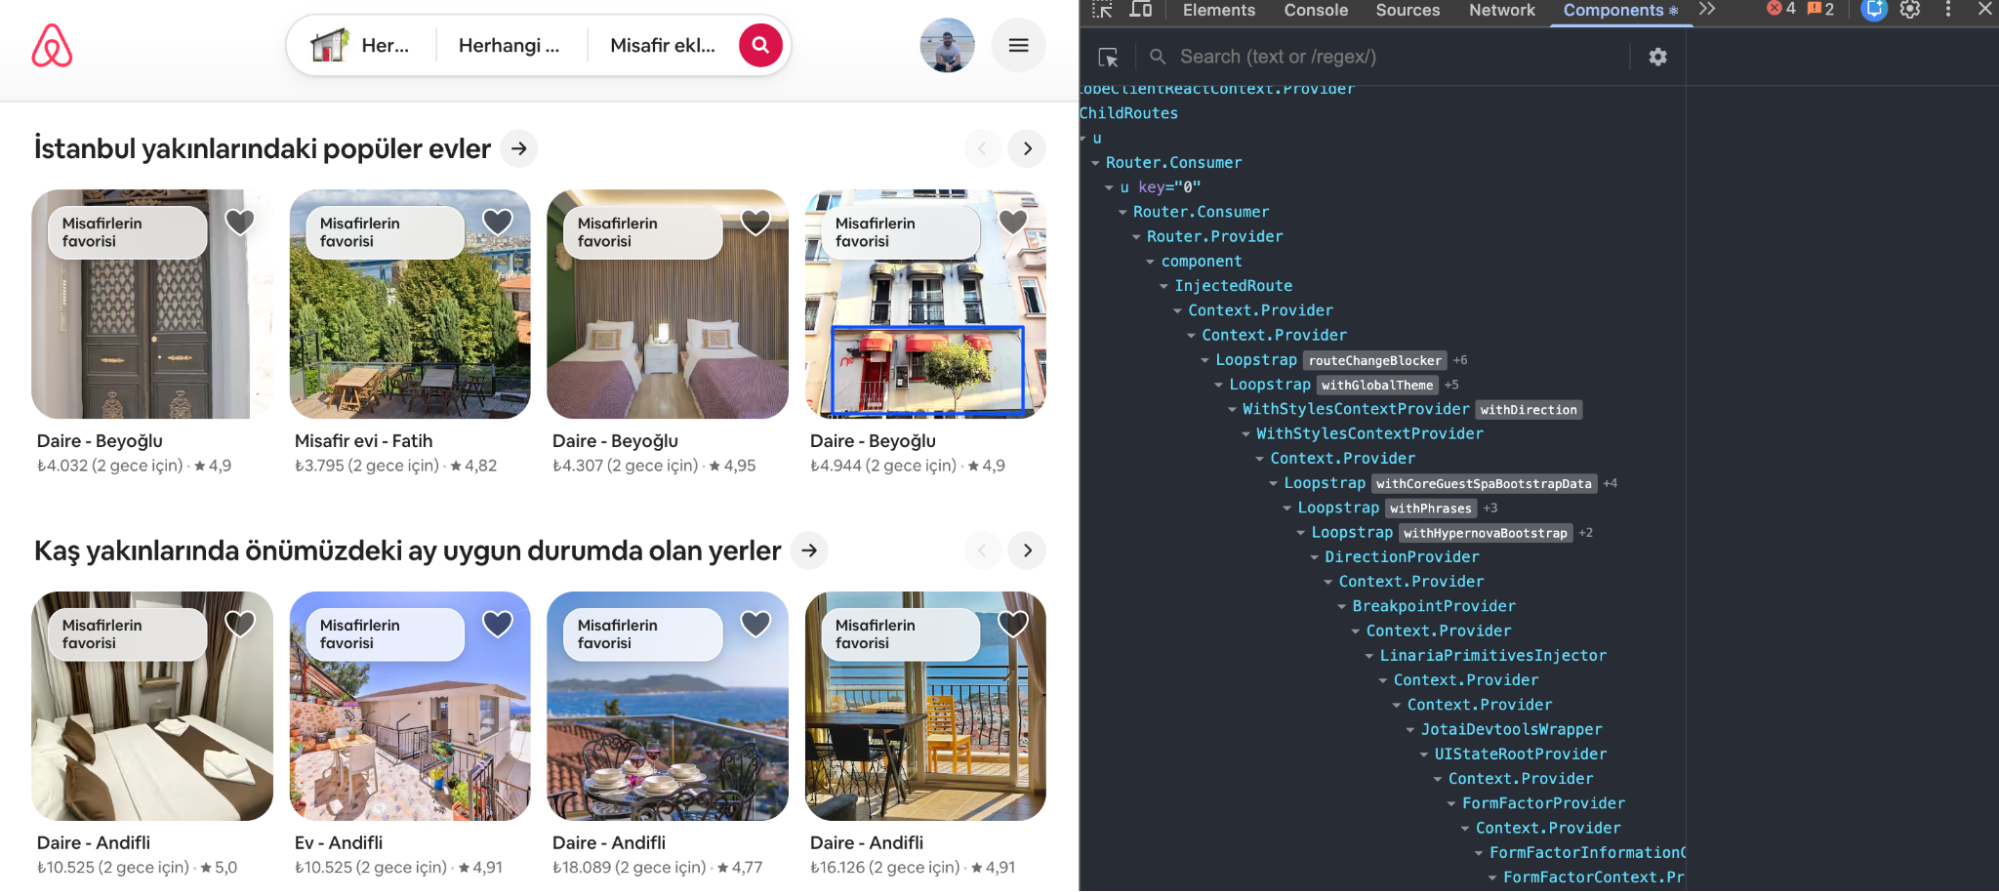
After this brief introduction, we can move on to React optimization. Below, you can see an example of a website built using the React framework;
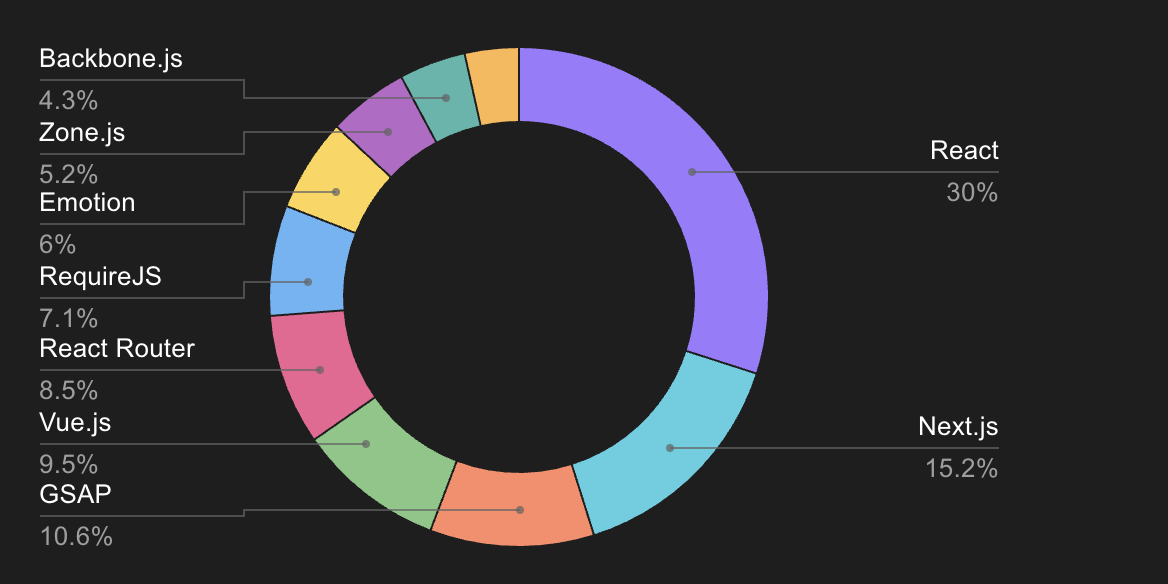
You can see which JS frameworks market leaders use in the example below. React ranks first. Just as Google can render other JavaScript frameworks, it can also render React.
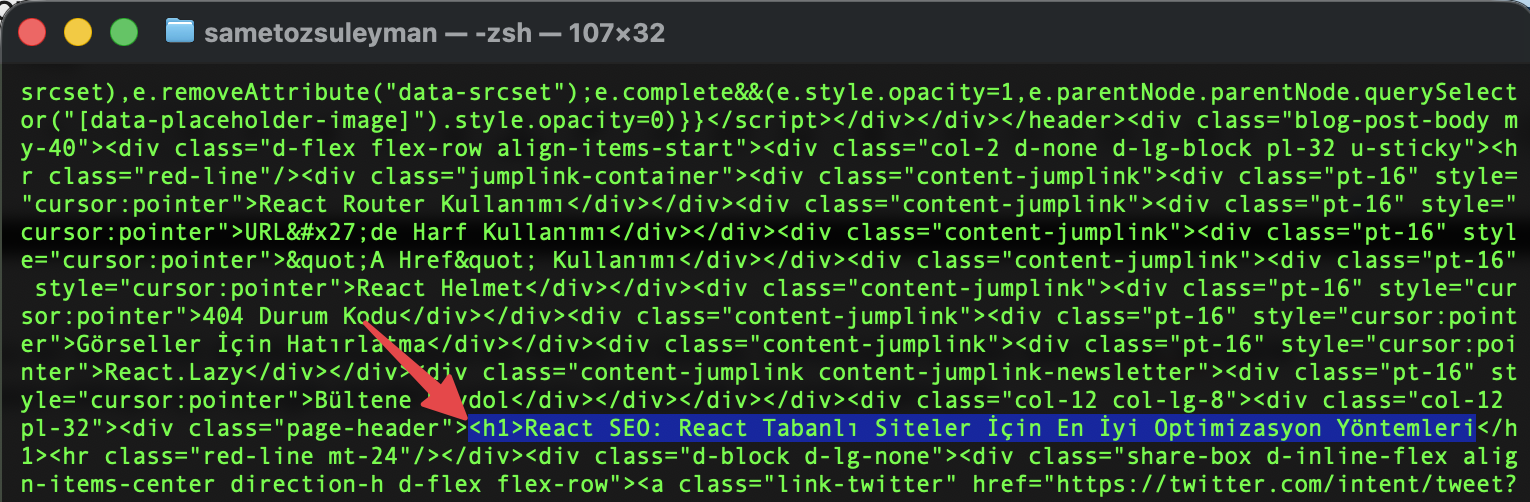
The page you are reading right now is also built with React. Since the content is already available in the raw HTML returned by the server, Google does not have to wait in the rendering queue:
Search Engines That Can and Cannot Execute JavaScript
Search engines such as Google and Bing can render at a much better level than they could in the past:
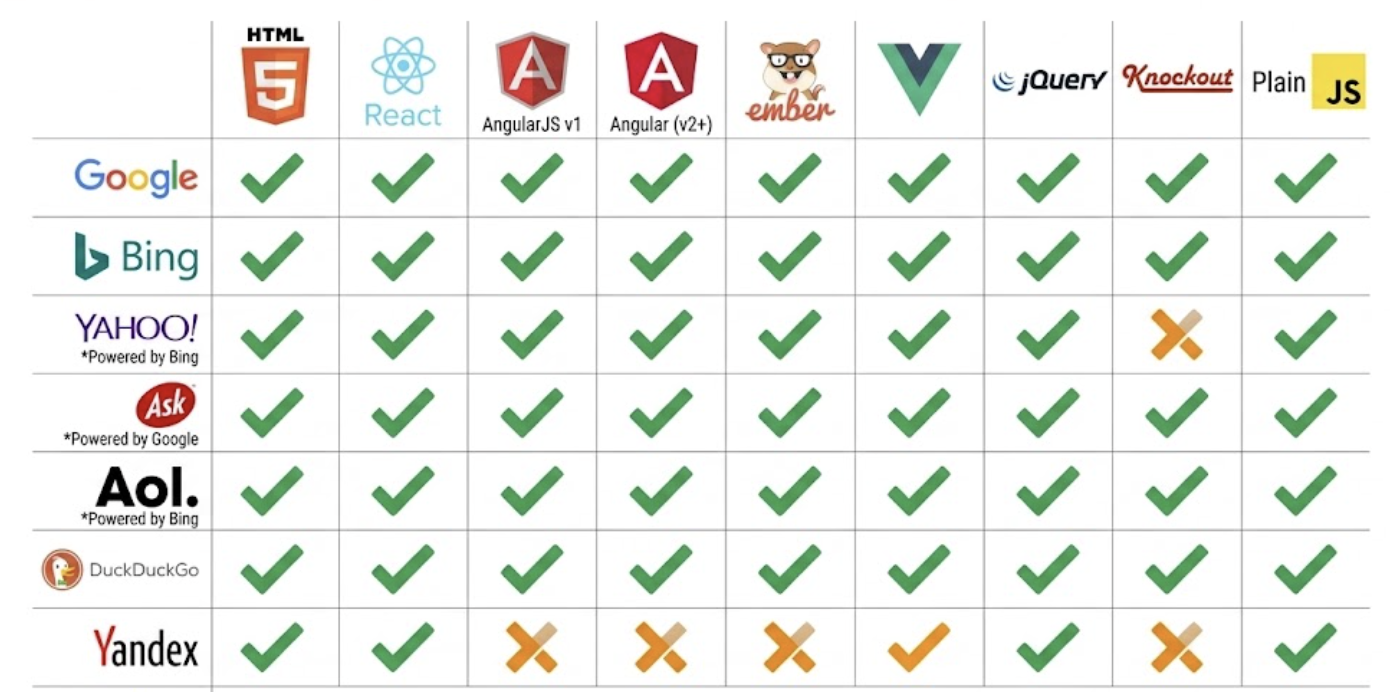
Googlebot can already render; however, in GEO work, we frequently analyze AI crawlers such as GPTBot, ClaudeBot, and PerplexityBot. You can review their CSR & SSR support in the table below:
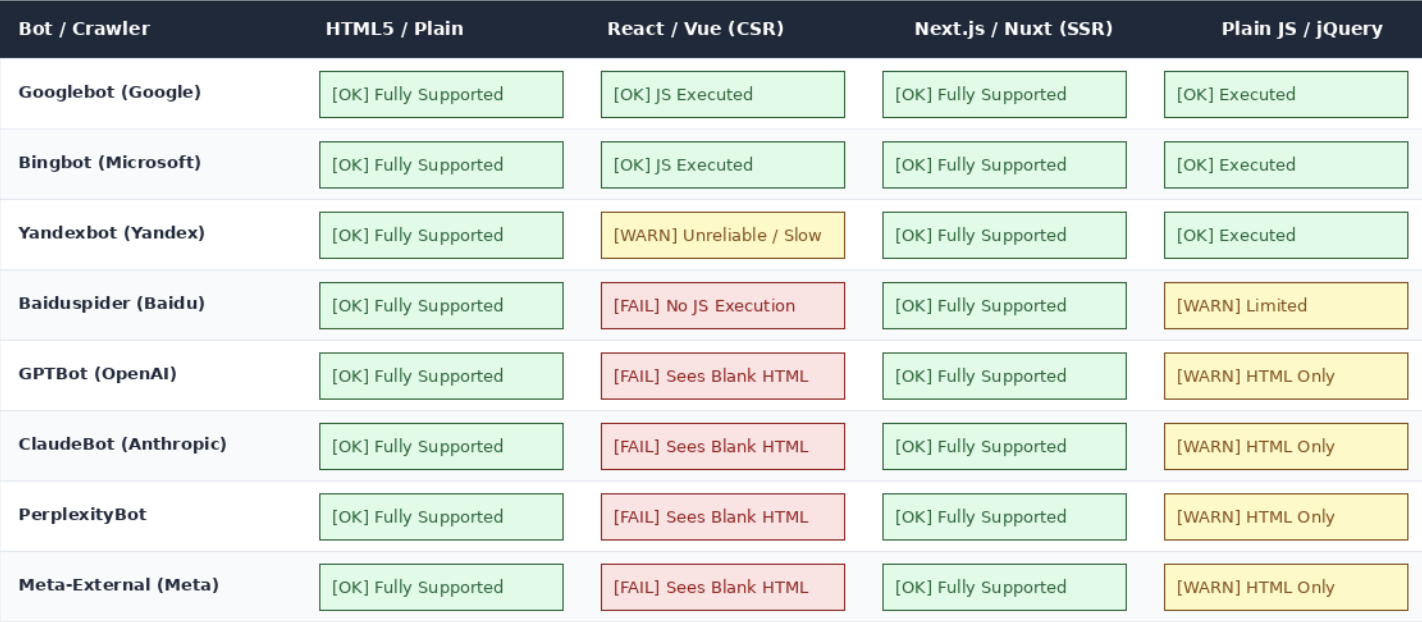
A page rendered with CSR may rank on Google but may never appear in LLM responses. You can check your pages with these details in mind.
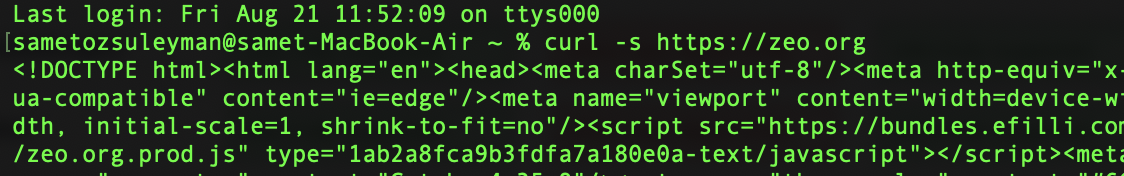
Our method for checking this is quite simple:
curl -s https://site.com - if there is no content in the terminal output, there is no content for bots either:
Rendering Strategy
Most SEO issues in React do not actually arise from choosing the wrong library, but from making the wrong rendering decision. When designing the strategy, I recommend making your decision based on the approaches below. I want to explain these terms in detail so that we can set up the entire system smoothly from the very beginning without running into problems:
CSR (Client-Side Rendering): The server sends an almost empty HTML document, and the JS in the browser creates the content. Everything looks normal to the user, but the HTML itself is completely empty.
SSR (Server-Side Rendering): The HTML is generated on the server for every request and delivered with the page content already populated. It is suitable for page types where prices, sizes, or stock availability change very frequently.
SSG (Static Site Generation): HTML is generated once during the build process, and the same file is then served to all bots. It is one of the fastest methods and has one of the lowest margins for error.
|
Page Type |
Recommended |
Why Do We Recommend It? |
|
Blog and corporate pages |
SSG |
The content on these pages changes rarely. |
|
PDP, PLP, or listing/vehicle listing pages |
SSR |
Prices and stock information change frequently, but these landing pages need to be indexed. |
|
Customer panel, my account, cart, checkout pages |
CSR |
They have no SEO requirements and do not need to be indexed. |
In short, I recommend not serving pages that need to appear on Google and especially in AI results with CSR. As you can see, we do not need to build the entire site with SSR; for example, you can use CSR on checkout pages. I deliberately included SSG for blog pages as well, because a 10-minute delay in reflecting a blog update will not be a problem; however, a 10-minute delay in a price update on an e-commerce site can cause issues. I think this summarizes the difference clearly.
Using React Router
As is well known, React embraces the SPA (single-page application) model; however, if we define certain rules and SEO elements properly on our pages, we can use the SPA model in a more advanced way.
It is very important for pages to open under separate URLs rather than in a # (hashtag) format. Since Google has stated that it cannot read hash-based URLs, if these kinds of URLs are created with React, Google may not index them. Therefore, each URL should be created so that it opens as a separate page.
Example of a hash-based URL that is not recommended: www.siteadi.com/#zeo-react
The correct action is to handle navigation through the History API. React Router provides this by default with BrowserRouter; if you use HashRouter, your URLs will contain hashes and these pages will not be indexed.
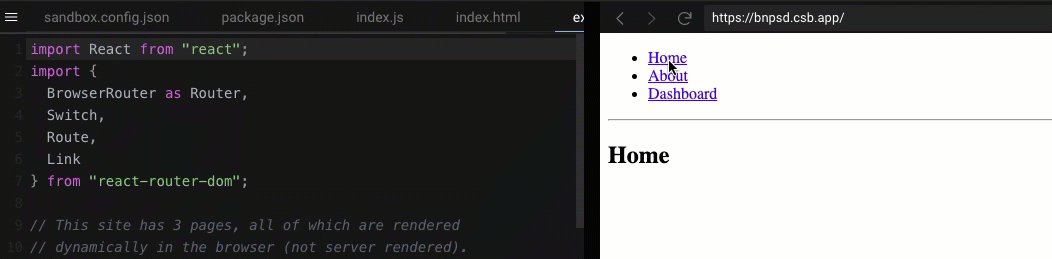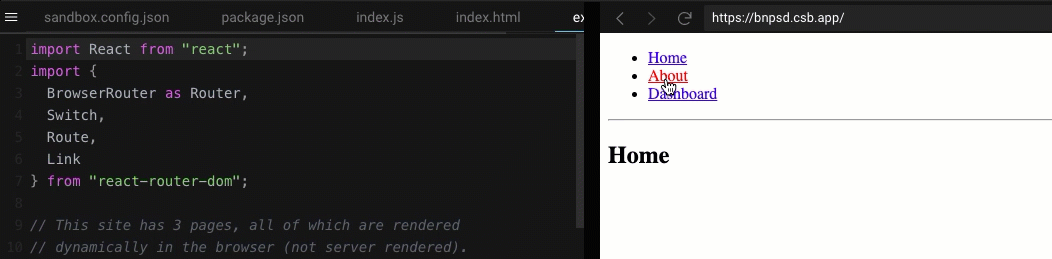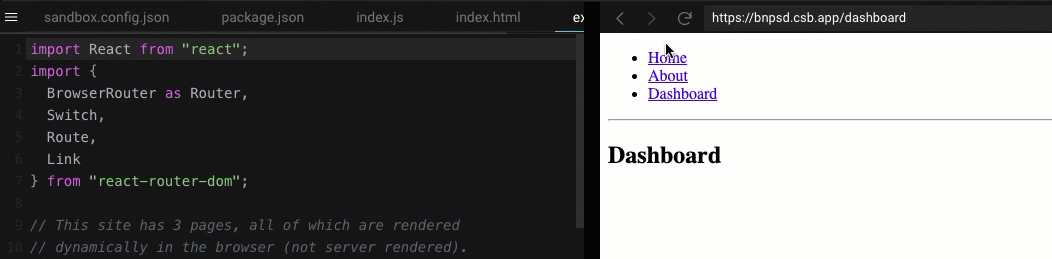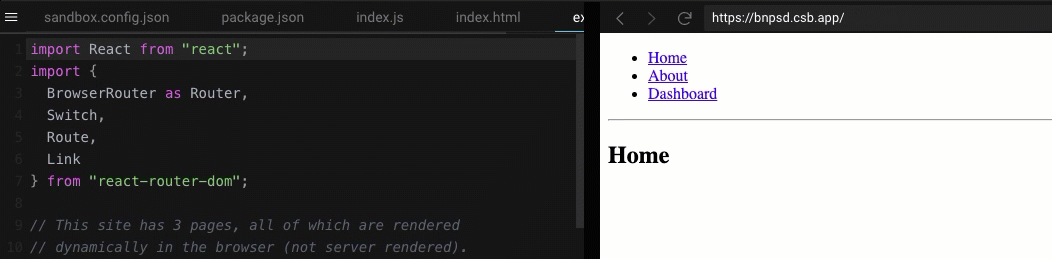
We should use React Router for URLs. You can find an example below;
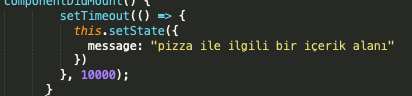
When creating content, we recommend avoiding a process where content is displayed after a certain number of seconds using setTimeout. In such cases, Googlebot may not remain on the page and may leave the site without reading the content, because G-Bot is a stateless visitor. It opens the page, sees the content, and leaves. It does not carry cookies or localStorage, and it does not respond to APIs that request notification permission.
Therefore, the content we want to be indexed should be ready at the initial render without any user interaction. For example, in cases where “the content loads when the visitor scrolls down”, Google may ignore the content:
If you use infinite scroll for pagination on PLPs and blog & news archive pages, I recommend applying the practices described in this article.
Using trailingSlash & middleware
Using uppercase/lowercase letters in URLs causes Google to treat these pages as separate pages. We see this especially often in React projects. Since routing is handled within the application, the router can map uppercase and lowercase variations to the same component and open the page without any issue; however, this creates a serious problem for us as SEO consultants.
My recommendation as an action is to build the URL structure using lowercase letters and without a trailing slash. In Next.js, you can add the code below in next.config.js. This will redirect requests that contain a trailing slash:
module.exports = {
trailingSlash: false,
};
A separate rule is also required for uppercase/lowercase handling. In Next.js, you can do this with middleware:
import { NextResponse } from "next/server";
export function middleware(request) {
const { pathname } = request.nextUrl;
if (pathname !== pathname.toLowerCase()) {
const url = request.nextUrl.clone();
url.pathname = pathname.toLowerCase();
return NextResponse.redirect(url, 308);
}
}
"Ahref" Usage in Links
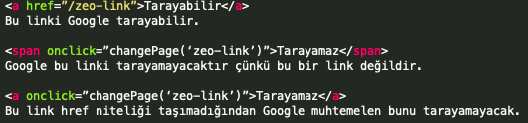
Links must always be provided using “a href”; Googlebot cannot read links provided with onclick. When Googlebot arrives on a page, links must be defined with a href so that it can find and visit other relevant pages.
Managing Metadata
Metadata, one of the fundamental building blocks of SEO, must be visible in the source code even when a React-based infrastructure is used. Using the same description and title structures may not provide benefits for CTR and other metrics;
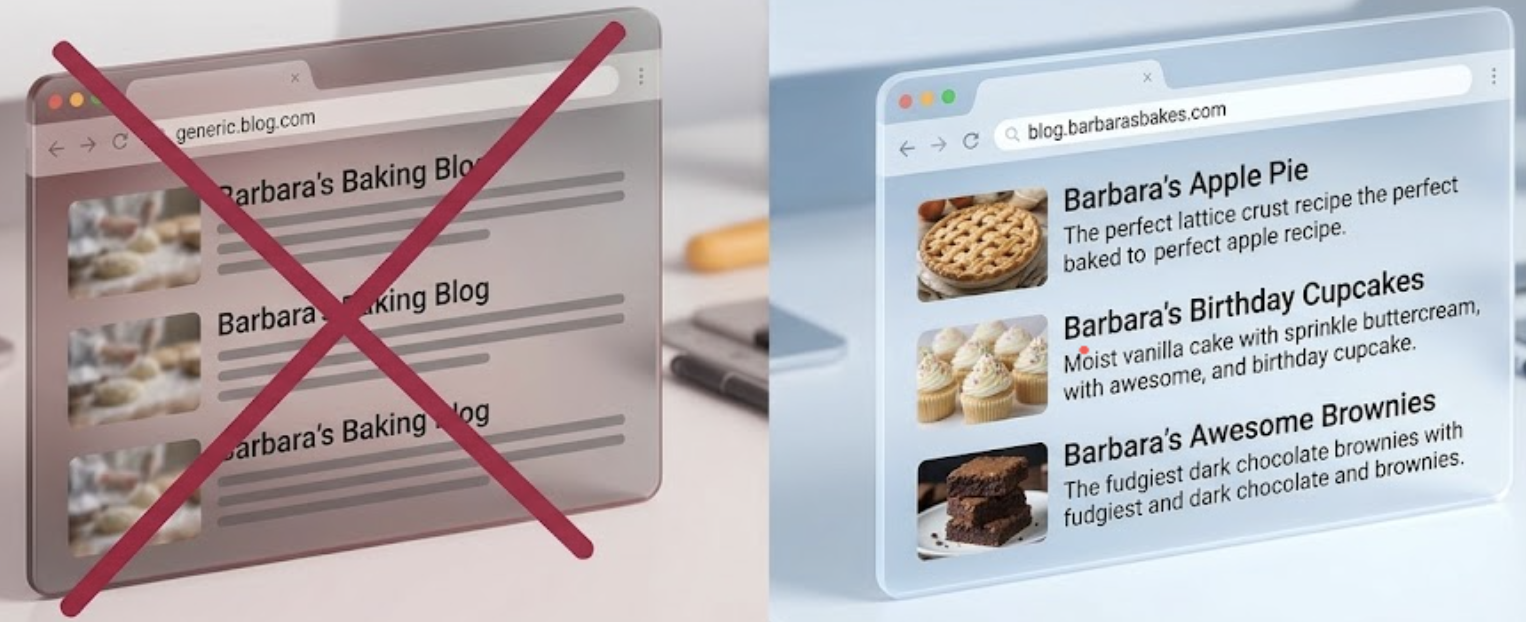 Image: Martin Splitt, React Developers
For many years, react-helmet was used for this purpose; however, the package is no longer actively maintained. If you use the Next.js App Router: Metadata API
export async function generateMetadata({ params }) {
const urun = await getUrun(params.slug);
return {
title: `${urun.ad} | Zeo Markası`,
description: urun.kisaAciklama,
alternates: { canonical: `https://zeo.org/urunler/${urun.slug}` },
openGraph: { images: [urun.gorsel] },
};
}
If you use the Next.js Pages Router: next/head
import Head from "next/head";
export default function Urun({ urun }) {
return (
<Head>
<title>{urun.ad} | Zeo Markası</title>
<meta name="description" content={urun.kisaAciklama} />
<link rel="canonical" href={`https://zeo.org/urunler/${urun.slug}`} />
</Head>
);
}
If you are not using a framework yet and have upgraded to React 19, you can render these meta tags anywhere, and React automatically moves them into the <head>:
function UrunSayfasi({ urun }) {
return (
<>
<title>{urun.ad} | Zeo Markası</title>
<meta name="description" content={urun.kisaAciklama} />
<link rel="canonical" href={`https://zeo.org/urunler/${urun.slug}`} />
<h1>{urun.ad}</h1>
</>
);
}
Cases where I definitely recommend testing:
- Canonical and, if applicable, hreflang must be present in the raw HTML.
- If noindex is present in the HTML and then removed after rendering, Google will use the first value it sees, so these pages will be removed from the index.
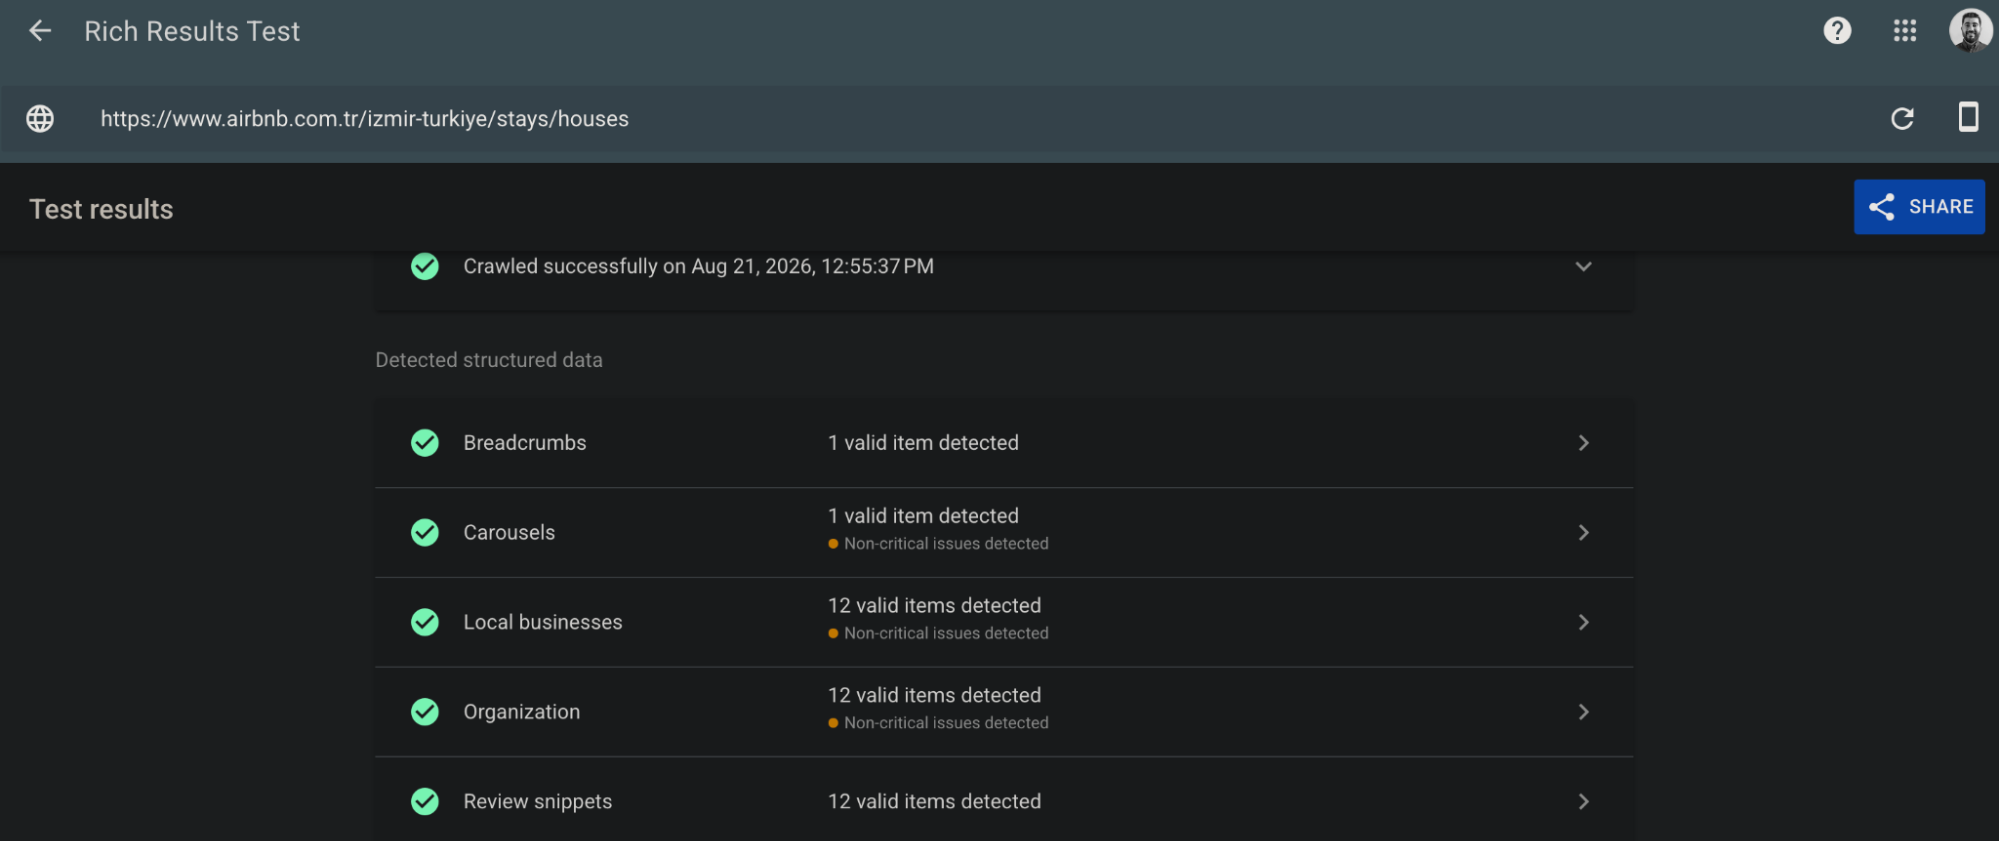
- Structured data should also be present in the HTML.
You can also test the page with the Rich Results Test to check whether Googlebot can see the structured data on the page:
Since dynamic rendering, which was previously recommended as a temporary solution, is no longer recommended by Google, I suggest choosing SSR or SSG for new projects or project migrations.
404 Status Code
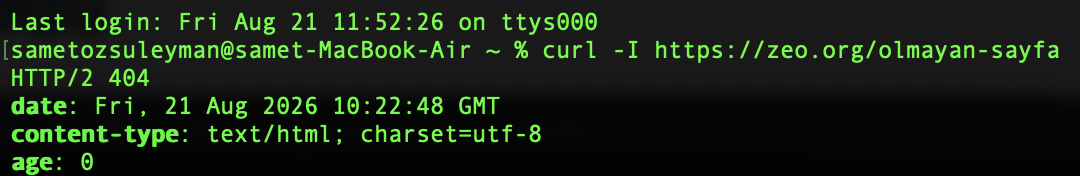
One of the most common mistakes I see is 404, one of the most fundamental SEO topics. Even if you display a “Page not found” screen, if the server returns a 200 status code, Google marks the page as a soft 404 and this creates a problem for crawl budget.
As an action on the server side, use notFound() in Next.js. If you manage your own server, unmatched routes should return a 404 status code.
You can check it in the terminal as follows: curl -I https://zeo.org/olmayan-sayfa
A Reminder for Images
On-site images must be specified with “img src”. Google has explained that even if Googlebot can display them correctly in its tools, it may not be able to index them.
Correct usage;
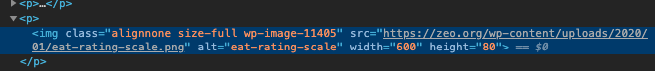
Using implementations such as CSS background together with React can cause problems with image indexing.
Incorrect usage;
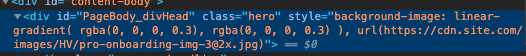
You can use next/image:
import Image from 'next/image'
export default function Page() {
return (
<Image
src="/profile.png"
width={500}
height={500}
alt="Picture of the author"
/>
)
}
React.lazy and Performance
Lazy loading is used for two different things in React projects, and the two should not be confused.
1) Lazy loading: There is no need for packages such as react-lazyload; the browser’s native loading="lazy" attribute is already sufficient. As we know from CWV analyses, we do not apply lazy loading to the LCP image anyway. next/image already handles these automatically.
2) React.lazy: React.lazy splits a component’s code into a separate chunk and makes the page’s initial load lighter. If comments are important to you and they load only after a button is clicked, Google will not see content loaded this way. I recommend using this carefully.
const QABolumu = lazy(() => import("./QABolumu"));
You can add splitting heavy components to your work plan. For example, you can split large components such as maps or video players with React.lazy. This way, the code is loaded only when needed, helping you optimize JavaScript size and improve the INP metric.
If I had to summarize SEO in React in one sentence: every detail that AI bots and search engines need to see should be present in the HTML returned by the server. You can think of these as metadata, canonical tags, schema code, images, main content, and links. If you have designed the rendering strategy I explained in the first section correctly, the rest is mostly detail :)


